1. Introduction: The GPU Arms Race in AI
*”OpenAI’s GPT-4.5 training reportedly used 25,000 H100s – but how do regular AI teams compete without billion-dollar budgets?”* This question haunts every startup. As AI models double in size every 6-10 months, GPU shortages have created a two-tier system: tech giants with unlimited resources, and everyone else fighting for scraps.
Here’s the good news: You don’t need corporate backing to access elite hardware. EmergingAI democratizes H100/H200 clusters with zero capital expenditure – delivering enterprise-grade performance on startup budgets. Let’s decode smart GPU strategies.
2. Why GPUs Dominate AI (Not CPUs)
GPUs aren’t just “faster” – they’re architecturally superior for AI:
| Feature | GPU Advantage | Real-World Impact |
| Parallel Cores | 20,000+ vs CPU’s 64 | 300x more matrix operations |
| Tensor Cores | Dedicated AI math units | H100: 1,979 TFLOPS (30x A100) |
| Memory Bandwidth | HBM3: 4.8TB/s vs DDR5: 0.3TB/s | No data starvation during training |
EmergingAI Hardware Tip:
*”Our H100 clusters deliver 30x speedups on transformer workloads versus last-gen GPUs.”*
3. NVIDIA’s AI GPU Hierarchy (2024)
Choose wisely based on your workload:
| GPU | VRAM | TFLOPS | Best For | EmergingAI Monthly Lease |
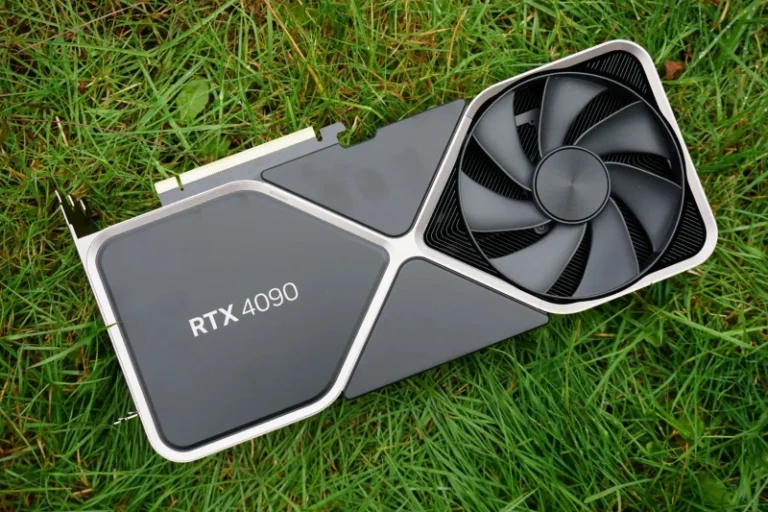
| RTX 4090 | 24GB | 82.6 | <13B model fine-tuning | $1,600 |
| A100 80GB | 80GB | 312 | 30B-70B training | $4,200 |
| H100 | 94GB | 1,979 | 100B+ model training | $6,200 |
| H200 | 141GB | 2,171 | Mixture-of-Experts | $6,800 |
4. Solving the GPU Shortage Crisis
Why shortages persist:
- TSMC’s CoWoS packaging bottleneck (50,000 wafers/month for global demand)
- Hyperscalers hoarding 350K+ H100s
EmergingAI Solution:
*”We maintain reserved inventory – deploy H200 clusters in 72hrs while others wait 6+ months.”*
5. Multi-GPU Strategies for Scaling AI
Avoid basic mistakes:
bash
# Bad: Forces all GPUs to same workload
docker run --gpus all
Advanced scaling with EmergingAI:
bash
EmergingAI deploy --model=llama3-70b \
                 --gpu=h200:4 \
                 --parallelism=hybrid
# Automatically optimizes:
# - Tensor parallelism (model weights)
# - Sequence parallelism (KV cache)
6. Hardware Showdown: Desktop vs Data Center GPUs
| Metric | RTX 4090 (Desktop) | H100 (Data Center) |
| 7B LLM Inference | 14 tokens/sec | 175 tokens/sec |
| VRAM Reliability | No ECC → Crash risk | Full error correction |
| Uptime | Days | Months (99.9% SLA) |
EmergingAI Recommendation:
*”Prototype on RTX 4090s → Deploy production on H100s/H200s”*
7. EmergingAI vs Public Cloud: TCO Breakdown
*Fine-tuning Llama 3 8B (1 week)*:
| Platform | GPUs | Cost | Preemption Risk |
| Public Cloud (Hourly) | 8x H100 | $12,000+ | High |
| EmergingAI (Lease) | 8x H100 | $49,600 | Zero (dedicated) |
*→ 58% savings with 1-month lease*
8. Optimizing GPU Workloads: Pro Techniques
Assign specific GPUs (e.g., InvokeAI):
python
os.environ["CUDA_VISIBLE_DEVICES"] = "1" # Use second GPU only
Track memory leaks, tensor core usage, and thermal throttling in real-time.
9. Future-Proofing Your AI Infrastructure
Coming in 2025:
- Blackwell architecture (4x H100 performance)
- Optical interconnects (lower latency)
EmergingAI Advantage:
“We cycle fleets every 18 months – customers automatically access latest GPUs without reinvestment.”
10. Conclusion: Beyond the Hype Cycle
Choosing AI GPUs isn’t about chasing specs – it’s about predictable outcomes. EmergingAI delivers:
- Immediate access to H100/H200 clusters
- 92% average utilization (vs. cloud’s 41%)
- Fixed monthly pricing (no hourly billing traps)
Stop overpaying for fragmented resources. Deploy optimized AI infrastructure today.