TL;DR: OpenClaw Cost Optimization
The Core Inefficiency: Most OpenClaw deployments waste 40-60% of their budget on Idle VRAM and unoptimized KV Cache storage during agent “thinking” cycles.
Strategic Pivot: Achieve a 70% TCO reduction by shifting from fixed-instance clusters to Intelligent Scaling and leveraging FP8/INT4 Quantization for inference-heavy workflows.
The Interconnect Factor: High-concurrency agents fail on standard cloud networks; EmergingAI’s 400Gb/s RDMA fabric ensures that data ingestion doesn’t inflate your billable GPU hours.
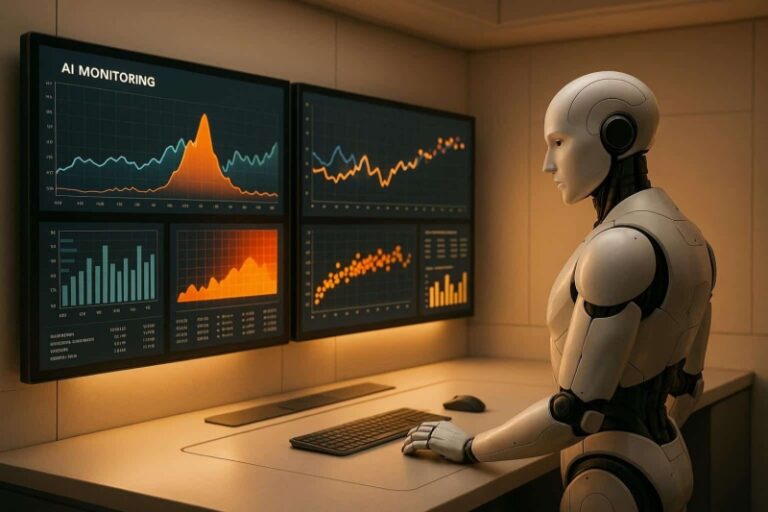
EmergingAI Advantage: Our Full-stack AI Observability identifies “Zombie Processes” in your OpenClaw stack, automatically reclaiming resources to ensure you only pay for active token generation.

1. Eliminate “Compute Ghosting” via Intelligent Scaling
The primary driver of high costs in OpenClaw isn’t the GPU price; it’s Compute Ghosting—the practice of keeping a high-performance node (like an H100) active while an agent is idling or waiting for API callbacks.
At EmergingAI, we solve this via Intelligent Scaling. Our platform monitors the OpenClaw request queue in real-time. When agentic activity drops, the workload is automatically migrated to a high-efficiency L4 or RTX 4090 node. This “Hot-Swapping” of compute tiers can slash monthly burn by 40% without compromising TTFT (Time-to-First-Token).
2. Quantization: Balancing Fidelity and Finance
Running OpenClaw on full FP16 precision is often a “budget killer” for 70B+ parameter models.
The Move:
Implement FP8 or AWQ Quantization. This reduces the VRAM footprint per model by nearly 50%, allowing you to fit larger context windows into a single GPU.
The ROI:
By doubling the density of agents per card, you effectively halve your hardware cost per user. EmergingAI nodes are pre-optimized for Transformer Engine FP8, ensuring that this precision drop has near-zero impact on agentic reasoning accuracy.
3. Observability-Driven Resource Reclammation
OpenClaw environments are notorious for “leaking” VRAM due to hung Python processes or unoptimized KV Caches in multi-turn conversations.
The EmergingAI Solution:
Our Deep Observability dashboard tracks Model Bandwidth Utilization (MBU) at the kernel level.
Actionable Fix:
If an OpenClaw instance shows 100% VRAM usage but 0% Compute utilization, EmergingAI triggers an automated Cache Purge or container restart, preventing “Frozen ROI” scenarios.
4. The OpenClaw Cost Matrix
| Strategy | Traditional Cloud (GCP/AWS) | EmergingAI Engineered Infrastructure |
| Scaling Model | Slow Auto-scaling Groups | Instant Intelligent Scaling |
| VRAM Management | Manual / Static | Automated KV Cache Orchestration |
| Interconnect | Shared 10-25GbE (Latency Bottleneck) | Dedicated 400Gb/s RDMA Fabric |
| Cost Control | Post-facto Billing Surprises | Real-time Token-per-Dollar Analytics |
| Total Savings | 0% (Baseline) | Up to 70% Reduction |
Expert FAQ
Q: Will reducing costs by 70% impact the latency of my agents?
A: No. The savings come from eliminating Resource Waste, not cutting performance. By using EmergingAI Intelligent Scaling, we ensure peak H200/H100 power is available instantly for “Prefill” phases while idling on cheaper silicon during “Decode” phases.
Q: How does EmergingAI handle “Cold Starts” when scaling OpenClaw?
A: We use Distributed NVMe Caching. Model weights are pre-staged in local high-speed buffers, reducing model load times from 60 seconds to under 5 seconds, ensuring your agents remain responsive.
Q: Can I monitor OpenClaw-specific metrics on EmergingAI?
A: Yes. Our Full-stack AI Observability integrates with common agent frameworks to track Token-to-Token (TBT)latency and Input-Output Ratios, giving you a granular view of your operational efficiency.